Quality metrics
Measured, not assumed
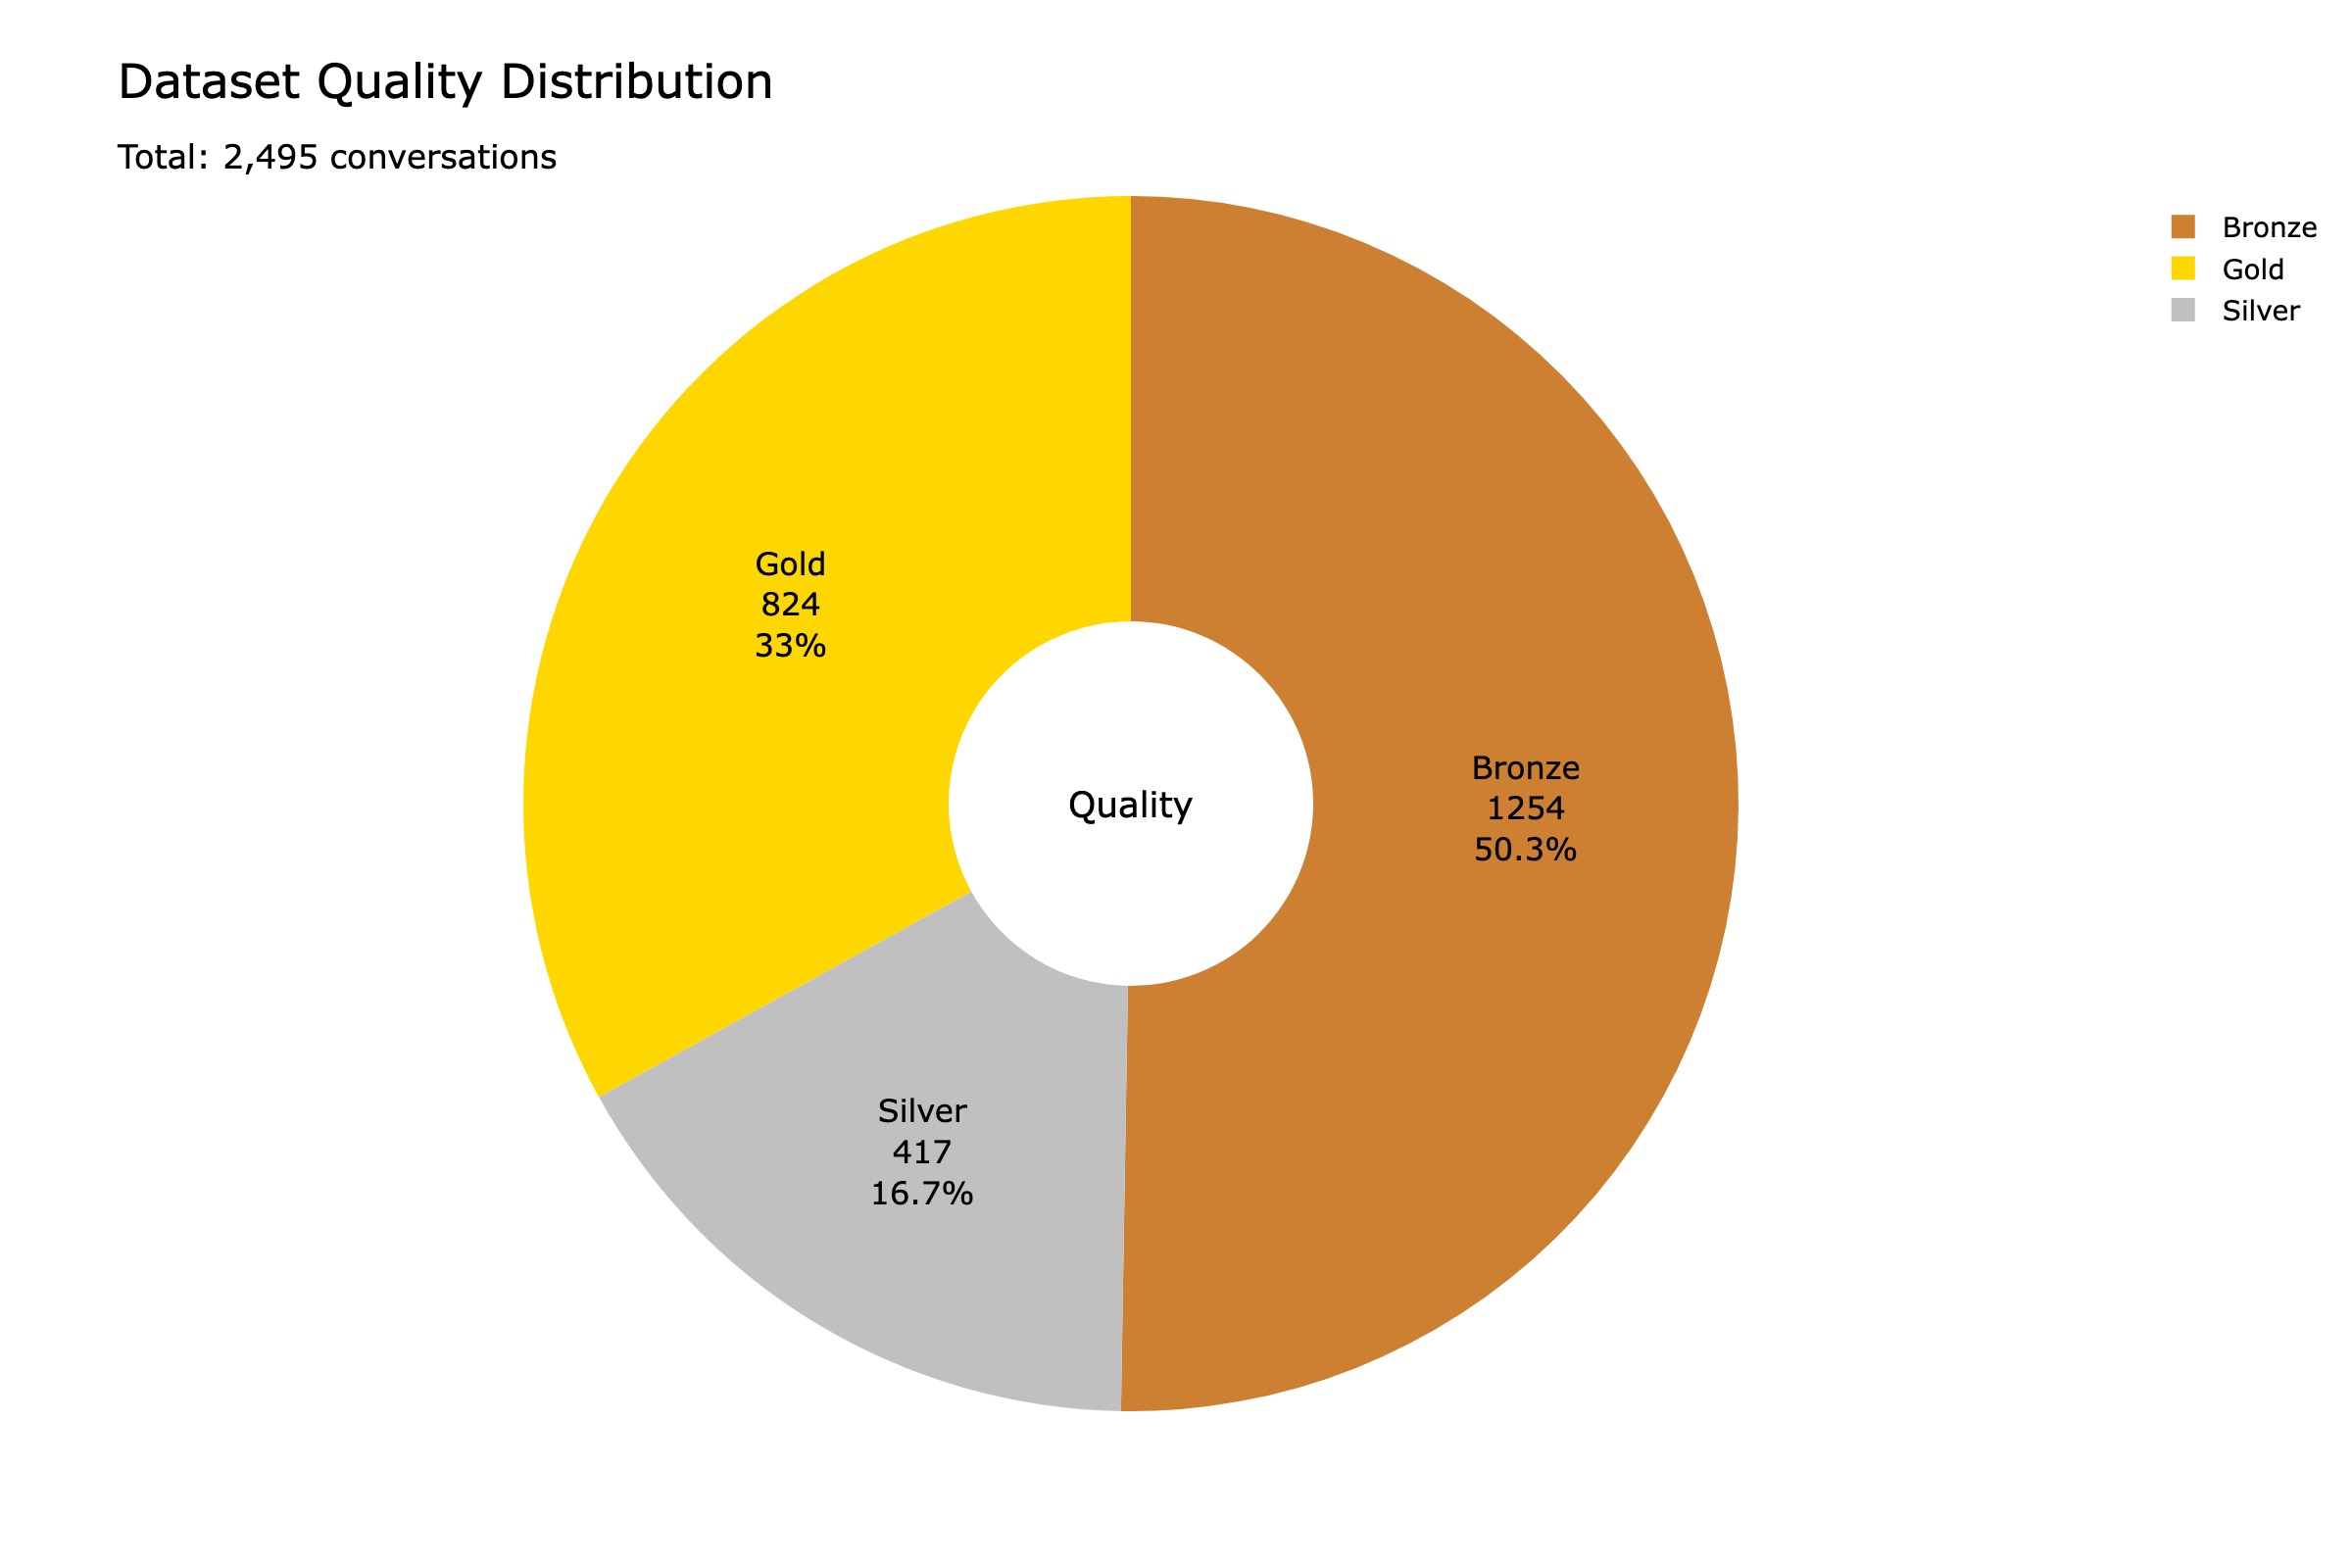
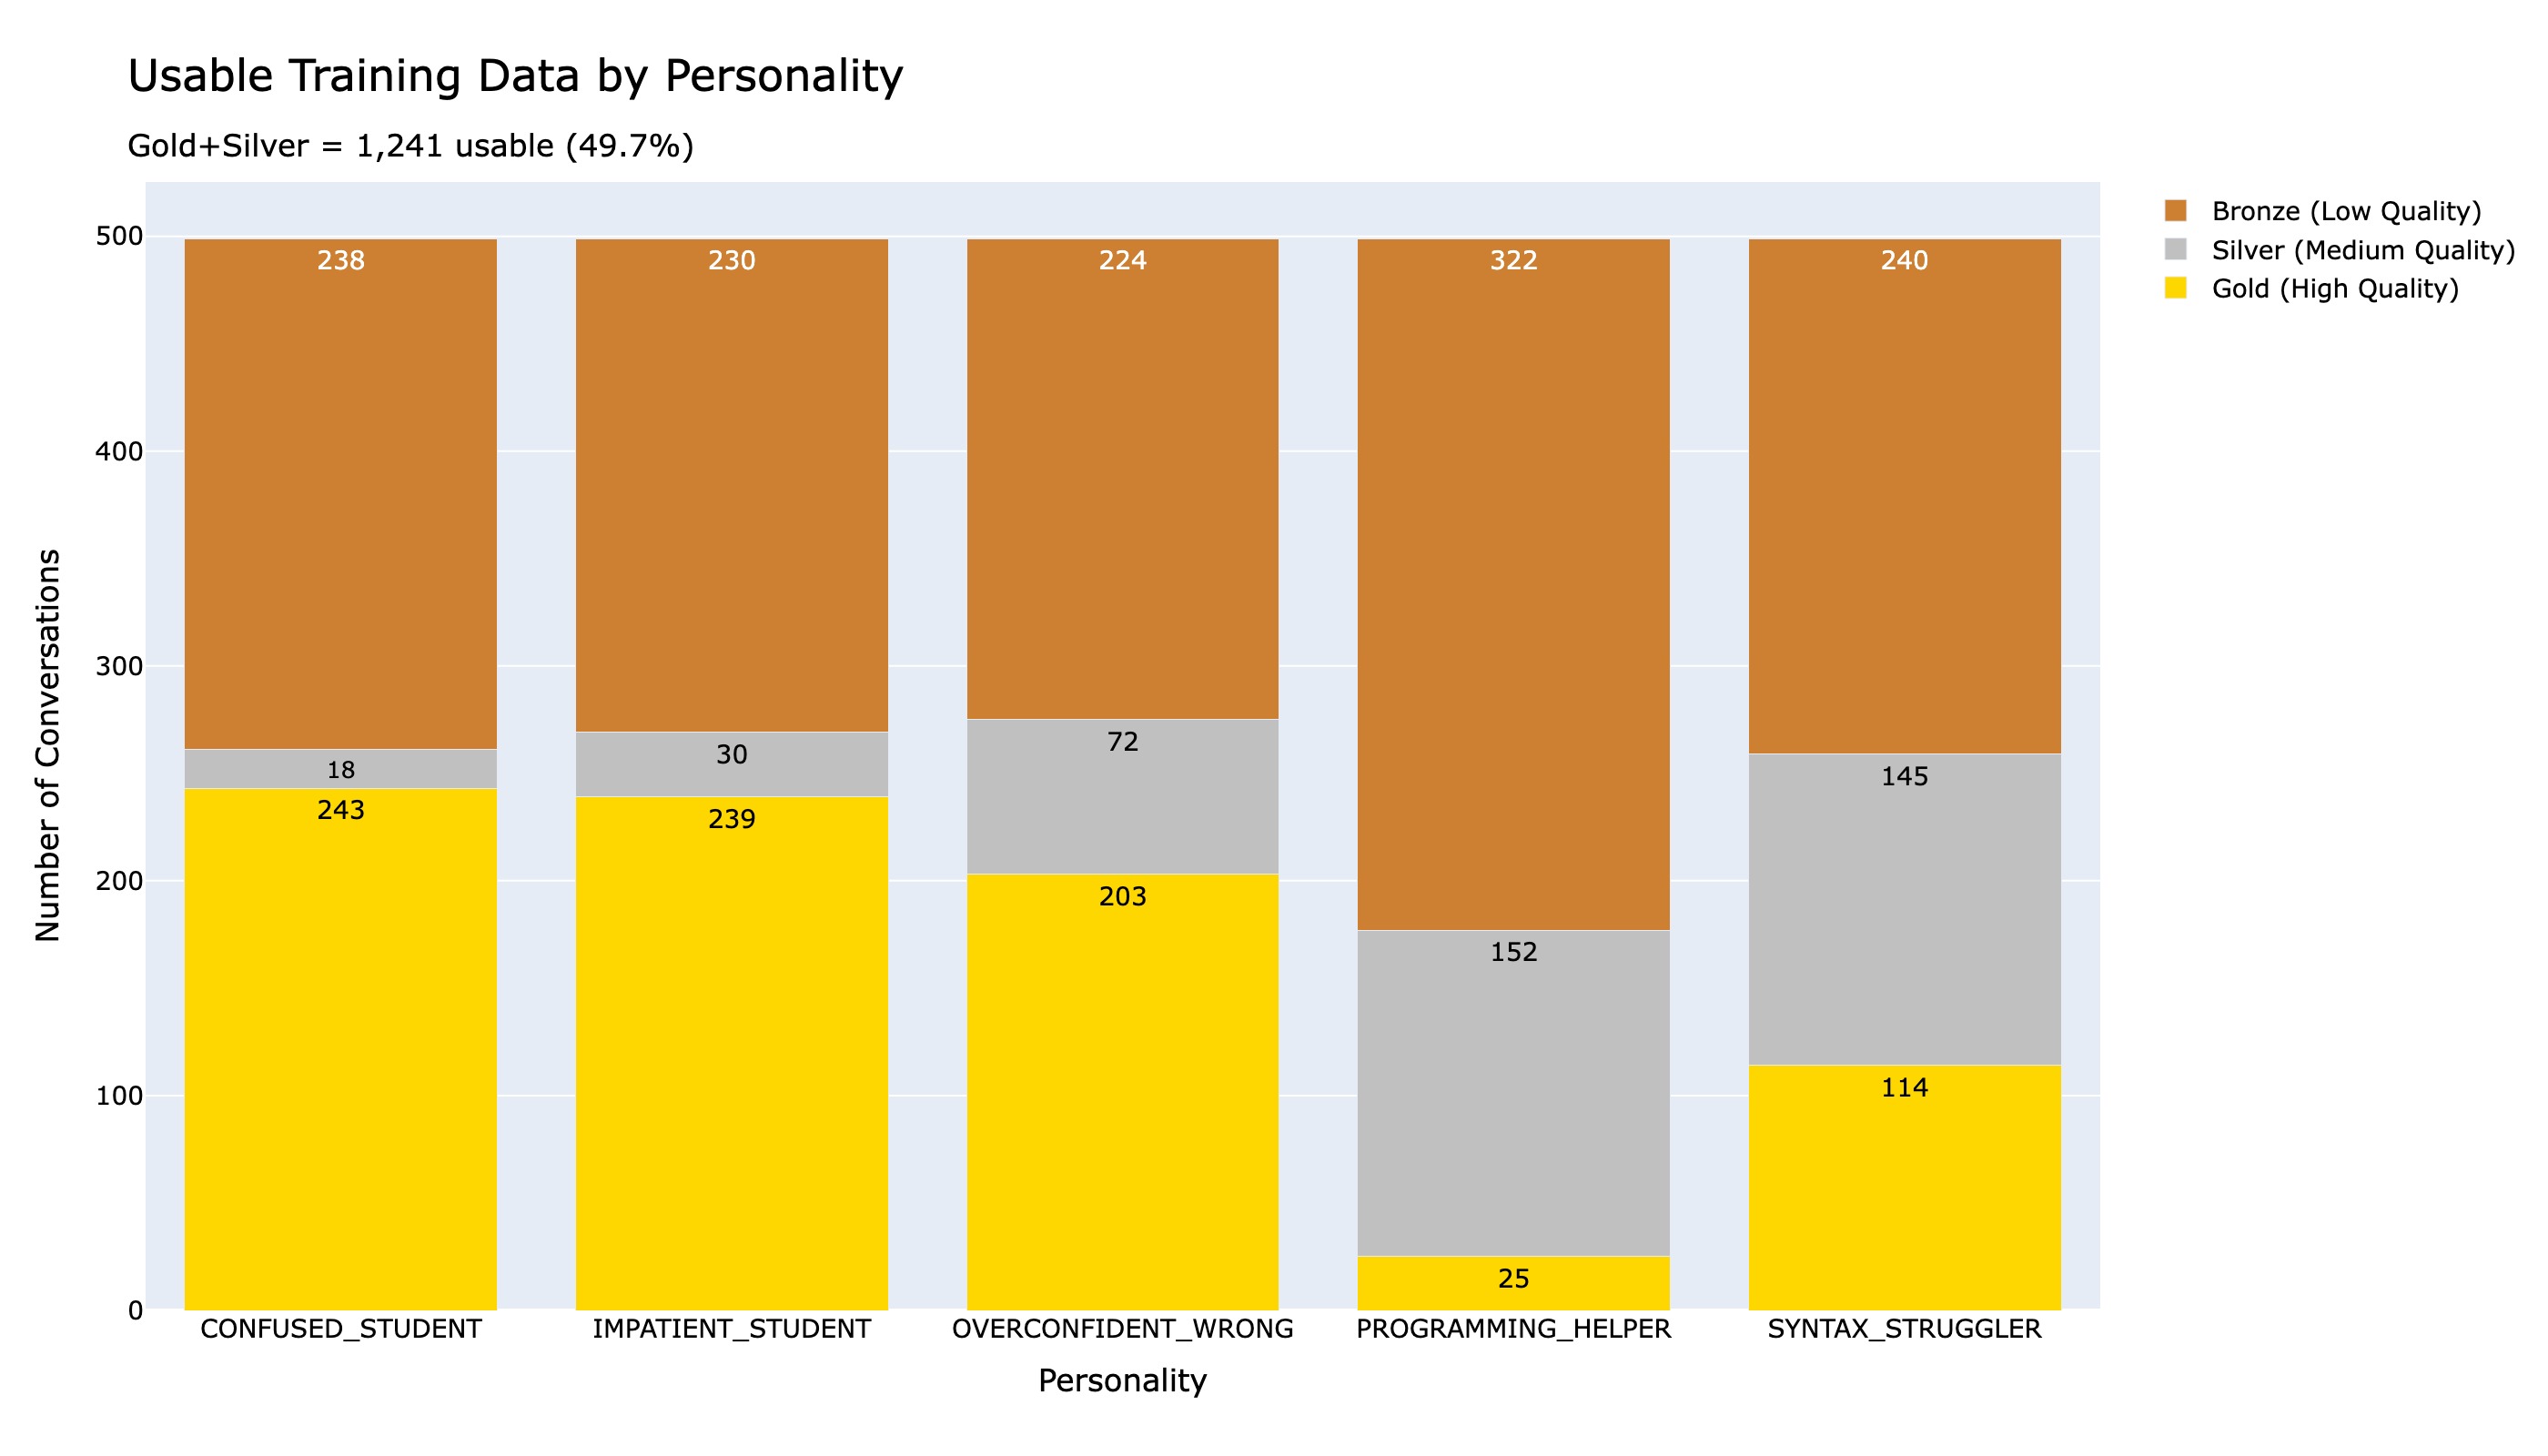
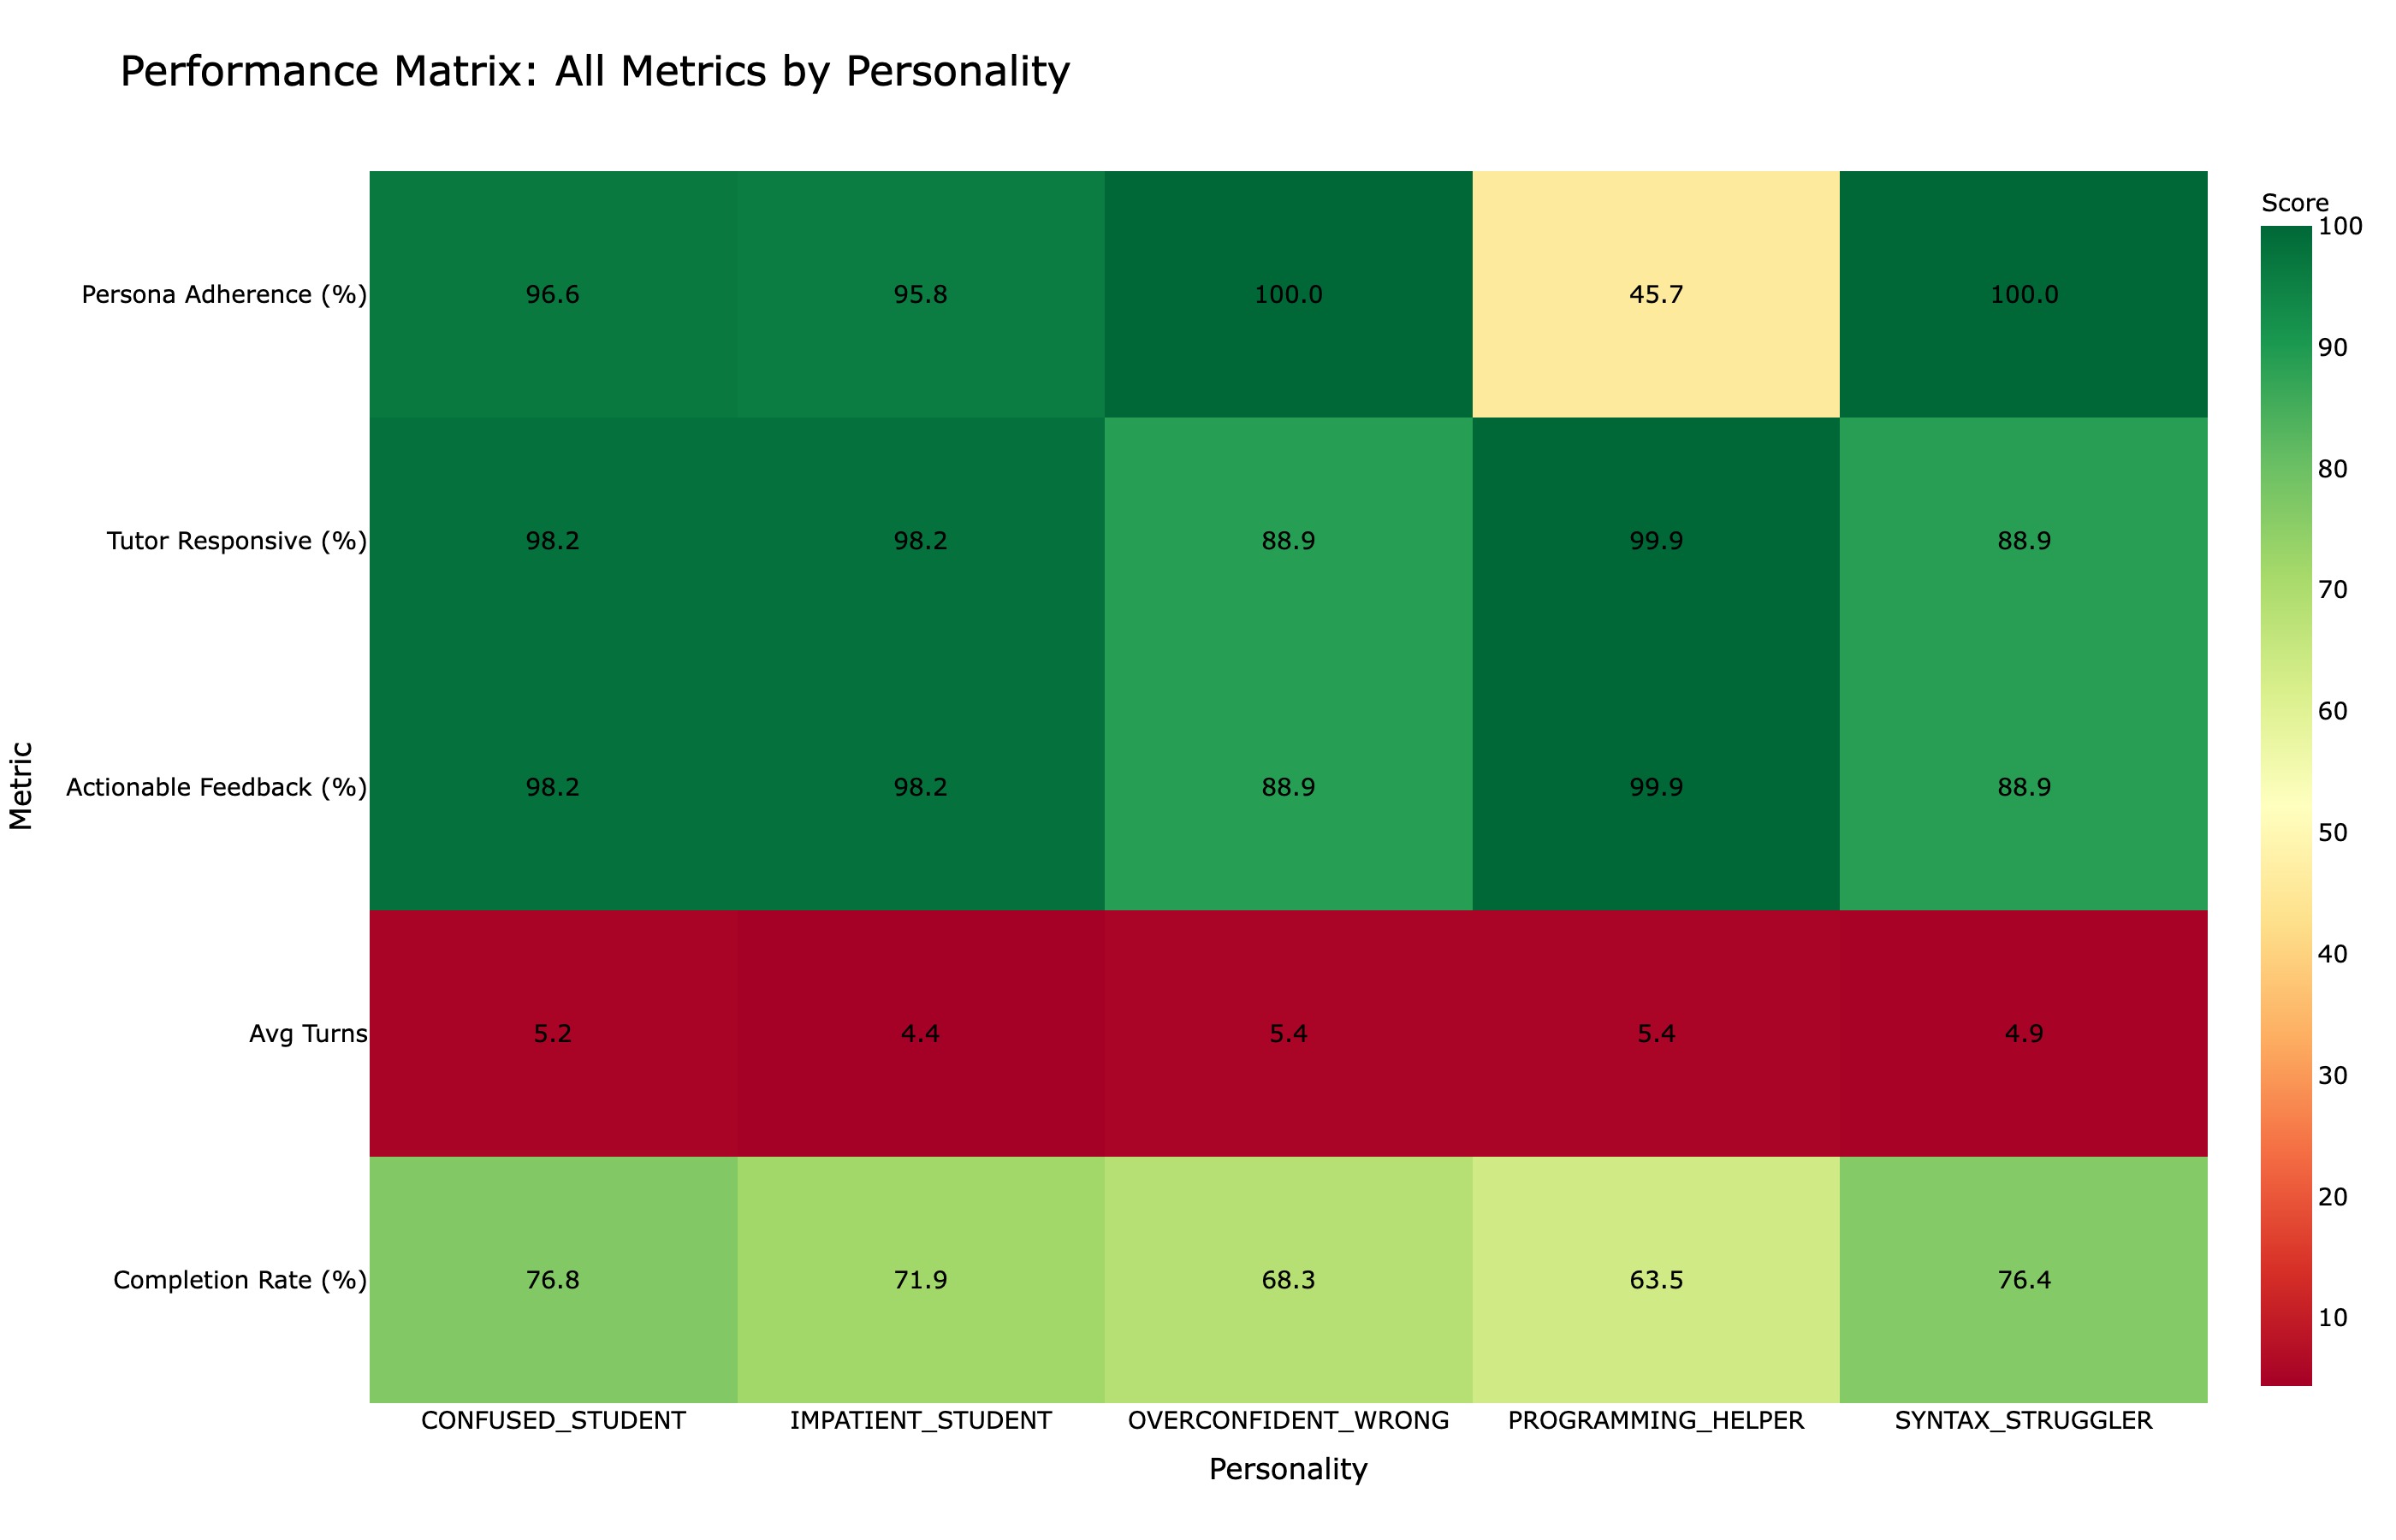
The three charts that best capture dataset health. Click any chart to enlarge.
An autonomous multi-agent pipeline that simulates student–tutor debugging sessions,
executes every candidate solution against real tests, and grades each conversation with
an LLM judge — producing data for fine-tuning coding tutors. The
strategy1_11_02_2026-Golden release contains 2,495 multi-turn debugging
conversations across five distinct student personalities —
the Confused, Impatient,
Overconfident, Syntax Struggler,
and Programming Helper.
2,495 conversations · 5 personalities · 500 problems
The dataset at a glance
Every conversation is generated, executed, and graded. Each of the 2,495 multi-turn debugging conversations is validated against pytest test cases and scored 0–10 by an LLM judge on persona fidelity, tutor responsiveness, and dialog flow.
Generation process
Two agents talk to each other. After each tutor response the code is executed against real tests; a router decides whether to keep debugging or stop.
One of 5 personalities asks or gives specific feedback.
Progressive refinement: incomplete early, complete later.
Runs the code under pytest against test cases.
Loops back or ends when solved / max turns.
Scores and assigns gold / silver / bronze.
The key trick
Naïve generation solved ~46% of conversations in 2 turns. Constraining the tutor turn-by-turn so early drafts must fail guarantees 4–6 turns of genuine back-and-forth.
| Turns | Max tokens | Temp | Instruction | Expected |
|---|---|---|---|---|
1–2 | 120 | 0.8 | 6–8 lines, ignore edge cases | Must fail tests |
3–4 | 300 | 0.6 | Fix only the named issue | Partial progress |
5+ | 500 | 0.3 | Handle all edge cases | Passes all tests |
Student agents
Lost but specific.
Direct and demanding.
Questions the tutor.
Fixated on syntax.
Expert who supplies fixes.
94.8% of student turns name a concrete code element (base case, loop, return, edge case).
See it for yourself
All 2,495 generated sessions. Pick a personality and quality, choose a conversation from the list, and read it with live execution results per turn. Quality reflects the debugging dialogue (persona fidelity, tutor responsiveness, flow) — not whether the final code passed, so a rich “gold” session can still end unsolved.
Loading conversations…
Quality metrics
The three charts that best capture dataset health. Click any chart to enlarge.